| ★ |  Fixing GPU Starvation in Large-Scale Distributed Training | | 321 | Reino Unido | |
| 2 |  Let's Build Pipeline Parallelism from Scratch – Tutorial | freeCodeCamp.org @freecodecamp | — | Estados Unidos | 89 |
| 20 |  OpenAI GPT 5.4 Leak Shocks The Internet With Massive Power | AI Revolution @airevolutionx | 120.9K | Estados Unidos | 86 |
| 4 |  Lessons From Training Composer At Cursor And Building Meta/Nvidia Compute Clusters | YC Paper Club | | 68.6K | Estados Unidos | 88 |
| 12 |  NVIDIA Blackwell & The 3nm Wall: Is AI Scaling Broken? | | 65.1K | Estados Unidos | 87 |
| 3 |  Stanford CS25: Transformers United V6 I The Ultra-Scale Talk: Scaling Training to Thousands of GPUs | Stanford Online @stanfordonline | 4.6K | Estados Unidos | 88 |
| 7 |  Keras 3 Distributed Training: Scaling Models with JAX using DataParallel, and ModelParallel | Google for Developers @googledevelopers | 3.1K | Estados Unidos | 87 |
| 16 |  This AI Ran 700 Experiments by Itself | What's AI by Louis-François Bouchard @whatsai | 2.0K | Canadá | 86 |
| 9 | 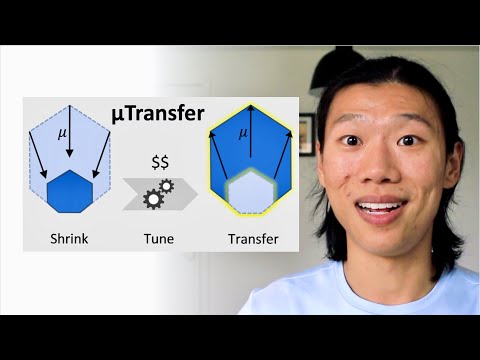 μTransfer: Tuning GPT-3 hyperparameters on one GPU | Explained by the inventor | | 1.6K | — | 87 |
| 6 |  Getting Humans Out of the Way: How to Work with Teams of Agents | | 1.0K | Reino Unido | 87 |
| 5 |  How We Cut LLM Latency 70% With TensorRT in Production | | 697 | Reino Unido | 88 |
| 1 |  Performance Optimization and Software/Hardware Co-design across PyTorch, CUDA, and NVIDIA GPUs | | 669 | Reino Unido | 89 |
| 18 |  Write Reliable Software with Temporal | | 621 | Reino Unido | 86 |
| 8 |  The Memory Problem Nobody's Talking About #datacenters #techtrends #serverlife | NextGen Science @thenextgenscience | 322 | Estados Unidos | 87 |
| 13 |  Uv Python Toolchain: From 100x Faster Packaging to OpenAI's Agent Runtime | | 168 | Estados Unidos | 87 |
| 17 |  The MATH of Running Humanity on GPUs (It's Cheap!) | Finxter AI Nuggets @finxter | 138 | Alemania | 86 |
| 19 |  The balance nobody achieves between storage and speed #servertech #engineering | NextGen Science @thenextgenscience | 94 | Estados Unidos | 86 |
| 11 |  The Real AI Bottleneck It’s Not GPUs It’s Memory Design and Math | NextGen Science @thenextgenscience | 67 | Estados Unidos | 87 |
| 15 |  SDUI at Scale: GraphQL & Elixir at Cars.com with Zack Kayser | | 48 | Estados Unidos | 87 |
| 14 |  Sharing and isolating GPU resources for AI workloads with Kubernetes DRA | Intel Open Source @intelopensource | 12 | Estados Unidos | 87 |
| 10 |  Showcasing WASM GPU Offload APIs | Intel Open Source @intelopensource | 4 | Estados Unidos | 87 |