| ★ |  Performance Optimization and Software/Hardware Co-design across PyTorch, CUDA, and NVIDIA GPUs | | 669 | Reino Unido | |
| 10 |  Let's Build Pipeline Parallelism from Scratch – Tutorial | freeCodeCamp.org @freecodecamp | — | Estados Unidos | 88 |
| 13 |  Coordinating Secure GPU-Accelerated Agents with Foundry Control Plane on Azure [APAC] | Microsoft Reactor @microsoftreactor | — | — | 88 |
| 1 |  Lessons From Training Composer At Cursor And Building Meta/Nvidia Compute Clusters | YC Paper Club | | 68.6K | Estados Unidos | 90 |
| 19 |  Optimizing the Full Stack for Generative Image and Video Models | MIT OpenCourseWare @mitocw | 12.1K | Estados Unidos | 87 |
| 9 |  Every AI Company Runs on NVIDIA Because of One Decision Made in 2006! | | 6.0K | Estados Unidos | 88 |
| 15 |  WWDC26: Optimize custom machine learning operations with Metal tensors | Apple | Apple Developer @appledeveloper | 4.7K | — | 88 |
| 4 |  Stanford CS25: Transformers United V6 I The Ultra-Scale Talk: Scaling Training to Thousands of GPUs | Stanford Online @stanfordonline | 4.6K | Estados Unidos | 89 |
| 20 |  Data Science Gamechanger? | | 2.5K | Estados Unidos | 87 |
| 18 |  Passer à la vitesse supérieure : Optimisation avancée de l'apprentissage (épisode 18) | CNRS - Formation FIDLE @cnrs-fidle | 1.2K | Francia | 87 |
| 17 |  How We Cut LLM Latency 70% With TensorRT in Production | | 697 | Reino Unido | 87 |
| 2 |  Fixing GPU Starvation in Large-Scale Distributed Training | | 321 | Reino Unido | 89 |
| 7 |  The MATH of Running Humanity on GPUs (It's Cheap!) | Finxter AI Nuggets @finxter | 138 | Alemania | 88 |
| 14 |  Edge Driven Generative AI Hardware Poised to Redefine Real Time Design | new technology insights @newtechnologyinsights-i9o | 135 | — | 88 |
| 11 |  Quantum Gradient Descent Accelerating Machine Learning Beyond Classical Computational Hardware Limit | NobleX Infinity Labs®️ @noblexinfinitylabs | 108 | India | 88 |
| 8 | 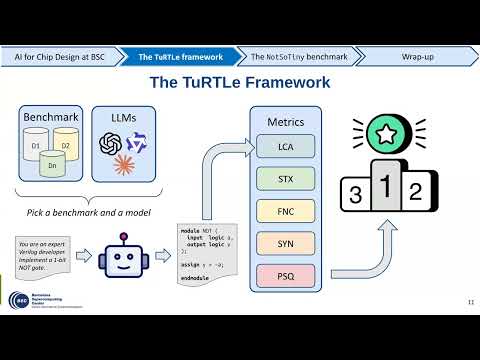 LOCA series: TuRTLe: Artificial Intelligence for Chip Design research at BSC | | 73 | España | 88 |
| 6 |  The Real AI Bottleneck It’s Not GPUs It’s Memory Design and Math | NextGen Science @thenextgenscience | 67 | Estados Unidos | 88 |
| 5 |  Optimize GPU Geometry with meshoptimizer: Complete Pipeline Explained | | 57 | Estados Unidos | 88 |
| 12 |  LOCA series: Optimal Silicon Efficiency in Servers | | 43 | España | 88 |
| 16 |  Understanding GPUs, TPUs, NPUs, and specialized AI chips (10 Minutes) | Microlearning Daily @microlearningdaily | 31 | Singapur | 87 |
| 3 |  Showcasing WASM GPU Offload APIs | Intel Open Source @intelopensource | 4 | Estados Unidos | 89 |