| ★ |  Keras 3 Distributed Training: Scaling Models with JAX using DataParallel, and ModelParallel | Google for Developers @googledevelopers | 3.1K | Estados Unidos | |
| 2 |  Let's Build Pipeline Parallelism from Scratch – Tutorial | freeCodeCamp.org @freecodecamp | — | Estados Unidos | 87 |
| 17 |  Deploying AI Models with Hugging Face – Hands-On Course | freeCodeCamp.org @freecodecamp | 75.0K | Estados Unidos | 85 |
| 7 |  PyTorch Tensors: The Data Structure Behind Deep Learning | | 16.9K | Estados Unidos | 86 |
| 5 |  TensorFlow Tutorial: From Tensors to Training | | 13.8K | Estados Unidos | 87 |
| 13 |  Deploying ML Models in 60 Minutes using Python, Flask & Render | Step-by-Step Tutorial | | 9.8K | India | 86 |
| 1 |  Build and Train an LLM with JAX | DeepLearningAI @deeplearningai | 7.0K | — | 88 |
| 8 |  Stanford CS25: Transformers United V6 I The Ultra-Scale Talk: Scaling Training to Thousands of GPUs | Stanford Online @stanfordonline | 4.6K | Estados Unidos | 86 |
| 11 |  Stop Fighting with Kubernetes! Scale Python to 1000s of Machines with Coiled | | 3.4K | India | 86 |
| 12 |  Keras Tutorial: Checkpointing distributed models with Orbax | Google for Developers @googledevelopers | 2.7K | Estados Unidos | 86 |
| 4 | 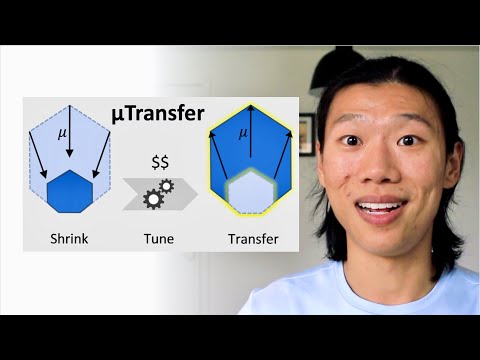 μTransfer: Tuning GPT-3 hyperparameters on one GPU | Explained by the inventor | | 1.6K | — | 87 |
| 19 |  Deploying Machine Learning Models: From Local Notebook to AWS Production | Analytics Vidhya @analyticsvidhya | 1.0K | India | 85 |
| 16 |  Neural Collaborative Filtering Code Walkthrough - Recommender System | DigitalSreeni @digitalsreeni | 786 | Estados Unidos | 85 |
| 14 |  Scaling Earth Engine Workflows - Best Practices for Large Scale Computations | Spatial Thoughts @spatialthoughts | 419 | India | 86 |
| 3 |  Fixing GPU Starvation in Large-Scale Distributed Training | | 321 | Reino Unido | 87 |
| 10 |  Track robotics training dynamics in Weights & Biases | Weights & Biases @weightsbiases | 284 | Estados Unidos | 86 |
| 20 |  Accelerate LLM post training with W&B Serverless SFT | Weights & Biases @weightsbiases | 282 | Estados Unidos | 85 |
| 15 |  Introduction to Amazon SageMaker Notebooks: Managed Jupyter for ML | Analytics Vidhya @analyticsvidhya | 209 | India | 85 |
| 6 |  Uv Python Toolchain: From 100x Faster Packaging to OpenAI's Agent Runtime | | 168 | Estados Unidos | 86 |
| 9 |  Cross-Entropy Loss Explained: The Complete Guide for Machine Learning | THE FACT FACTORY @thefactfactoryf | 37 | — | 86 |
| 18 |  Deploying Large Language Model Serving and Fine-Tuning Services using BigDL-LLM on Kubernetes | Intel Open Source @intelopensource | 8 | Estados Unidos | 85 |