| ★ |  Shared Parameters - CNNs | | 451 | India | |
| 18 |  Lec 20. Scaling Laws | MIT OpenCourseWare @mitocw | — | Estados Unidos | 82 |
| 15 |  China Just Dropped 1 Trillion Parameter AI Model That Shocks OpenAI | AI Revolution @airevolutionx | 113.2K | Estados Unidos | 83 |
| 10 |  How AI connects text and images | | 37.8K | Estados Unidos | 83 |
| 5 |  Lec 07. Scaling Rules for Optimization | MIT OpenCourseWare @mitocw | 5.9K | Estados Unidos | 84 |
| 8 |  Keras 3 Distributed Training: Scaling Models with JAX using DataParallel, and ModelParallel | Google for Developers @googledevelopers | 3.1K | Estados Unidos | 83 |
| 20 |  The Unsung Hero of AI: Vector Embeddings | Till Musshoff @tillmusshoff | 2.0K | — | 82 |
| 7 | 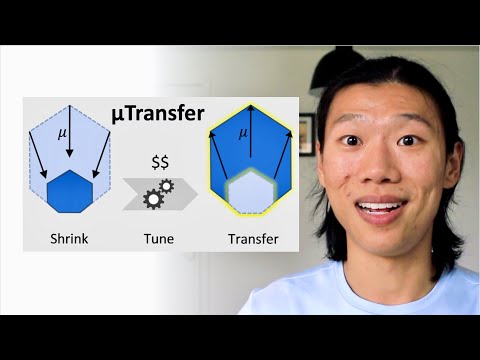 μTransfer: Tuning GPT-3 hyperparameters on one GPU | Explained by the inventor | | 1.6K | — | 84 |
| 3 |  LoRA - Explained! | CodeEmporium @codeemporium | 1.3K | Estados Unidos | 84 |
| 9 |  120 Billion Parameters: The Model Size Debate Explained! #shorts | Pew Moments @pewmoments90210 | 1.1K | — | 83 |
| 4 |  LLM (Parameter Efficient) Fine Tuning - Explained! | CodeEmporium @codeemporium | 558 | Estados Unidos | 84 |
| 16 |  Why convolution networks work so well (on images) | CodeEmporium @codeemporium | 485 | Estados Unidos | 82 |
| 1 |  From Feature Maps to Predictions: Flatten Layer EXPLAINED #MLbasics #neuralnetworks | | 261 | India | 85 |
| 11 |  Where the Score Lives: What Wavelets Reveal About Diffusion Models | Microsoft Research @microsoftresearch | 184 | Estados Unidos | 83 |
| 2 |  CNNs Pooling | | 151 | India | 84 |
| 14 |  Deep Image Retrieval: Learning global representations for image search | Xavi Giró-i-Nieto @xavigiro-i-nieto | 104 | — | 83 |
| 19 |  Cross-Entropy Loss Explained: The Complete Guide for Machine Learning | THE FACT FACTORY @thefactfactoryf | 37 | — | 82 |
| 17 |  Federated Learning Unveiled Local Data Global Gains | | 34 | — | 82 |
| 13 |  Premio Nobel de Física 2024: La inteligencia artificial y el aprendizaje automático redes neuronales | Todos Juntos Aprendiendo @tjaprendiendo | 33 | México | 83 |
| 12 |  Why Weight Decay IS L2 Regularization: Complete Guide Explained | THE FACT FACTORY @thefactfactoryf | 5 | — | 83 |
| 6 |  Deep Learning - Question 4 - What is the difference between "hyper-parameter" and "parameter"? | Emre KOCYIGIT @emre_kocyigit | 3 | Luxemburgo | 84 |