| ★ |  New fine-tuning of language models: Match meaning, not tokens | Microsoft Research @microsoftresearch | 379 | Estados Unidos | |
| 12 |  Stanford CS25: Transformers United V6 I From Language Models to Native Multimodal Intelligence | Stanford Online @stanfordonline | 198.7K | Estados Unidos | 88 |
| 7 |  Stanford CS25: Transformers United V6 I From Next-Token Prediction to Next-Generation Intelligence | Stanford Online @stanfordonline | 33.7K | Estados Unidos | 89 |
| 9 |  9: Generative AI – Large Language Models (LLMs) and Retrieval Augmented Generation (RAG) | MIT OpenCourseWare @mitocw | 13.1K | Estados Unidos | 89 |
| 20 |  10: Generative AI – Adapting LLMs with Parameter-Efficient Fine-Tuning | MIT OpenCourseWare @mitocw | 9.3K | Estados Unidos | 88 |
| 18 |  Stanford CS25: Transformers United V6 I Distinct Modes of Generalization from Parameters and Context | Stanford Online @stanfordonline | 4.4K | Estados Unidos | 88 |
| 16 |  Lec 21. Language Models | MIT OpenCourseWare @mitocw | 2.2K | Estados Unidos | 88 |
| 3 |  Chain-of-thought prompting - Explained! | CodeEmporium @codeemporium | 1.1K | Estados Unidos | 90 |
| 10 |  LLM (Parameter Efficient) Fine Tuning - Explained! | CodeEmporium @codeemporium | 558 | Estados Unidos | 89 |
| 19 |  Una introducción a los límites de los modelos de lenguaje para el trabajo científico | El Colegio de México A.C. @videoscolmex | 554 | México | 88 |
| 6 |  AI Agent Specialization. RAG vs Fine-tuning - T3chFest 2026 | | 438 | España | 89 |
| 11 |  This week - #machinelearning papers you should know about | | 359 | India | 89 |
| 13 |  Belief, Uncertainty, and Truth in Language Models | The Berkman Klein Center for Internet & Society @bkcharvard | 307 | Estados Unidos | 88 |
| 8 | 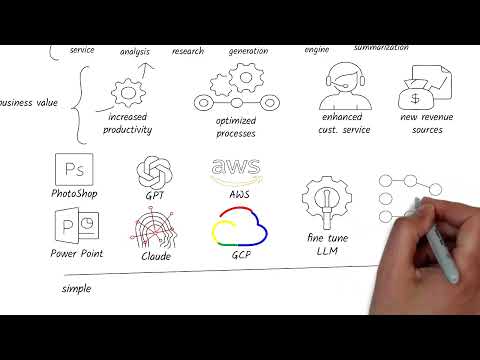 For the Leader Architect: Why your organization needs fine-tuned Generative AI LLMs? | | 258 | Estados Unidos | 89 |
| 1 |  Matching features, not tokens: Energy-based fine-tuning of language models | Microsoft Research @microsoftresearch | 96 | Estados Unidos | 94 |
| 15 |  Day 1 of Language Models : AI Predicts Words (Before ChatGPT) Language Model - Introduction to LLMs | | 64 | India | 88 |
| 2 |  Large Language Models for Real-World Applications | | 24 | Estados Unidos | 90 |
| 5 |  Demo: Large Language Models for Real-World Applications | | 17 | Estados Unidos | 89 |
| 14 |  Unlocking AI: The Power of Enhanced Language Models | Groping The Elephant @gropingtheelephant | 4 | — | 88 |
| 4 |  "ChatGPT Showdown: Unraveling the Key Differences Between GPT-3 and GPT-4 for AI Enthusiasts" | | 0 | Estados Unidos | 89 |
| 17 |  Charla de Felipe Bravo-Márquez: "Tackling Fairness, Change and Polysemy in Word Embeddings" | | 0 | Chile | 88 |